
‘Building Fast’ While ‘Building Competently’ Remains Key, Expert Says
By Mathew J. Schwartz (euroinfosec)
Questions over the risk posed by artificial intelligence and accompanying safety, security and reliability concerns dominated this year’s RSAC Conference in San Francisco.
Seemingly every vendor product now is AI-enabled, which can mean many things – from large language models used to analyze data sets, to generative AI for creating realistic-looking and sounding text, audio and video, to agentic agents designed to act autonomously.
Wider debate rages over the extent to which safety and security concerns might be holding back AI innovation for the masses. Speaking at the AI Action Summit in Paris in February, US Vice President JD Vance said the world’s focus should be on AI opportunities. “The AI future is not going to be won by hand-wringing about safety,” he said.
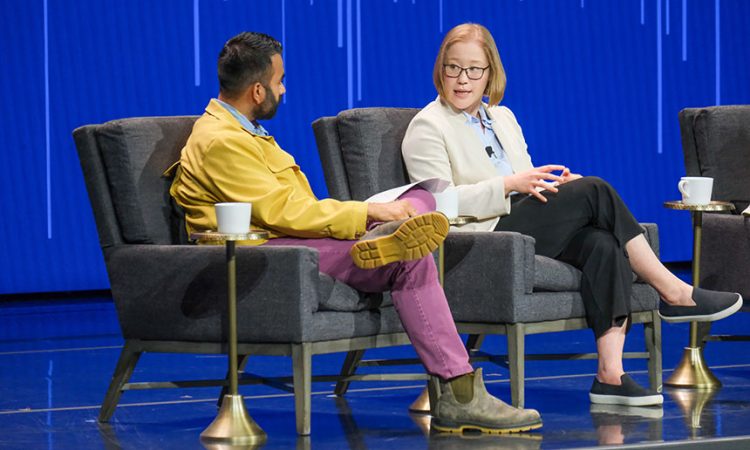
Vance’s comment featured in the “AI Safety: Where Do We Go From Here?” panel at RSAC Conference on April 29, when moderator Ram Shankar Siva Kumar, a self-described “data cowboy” who founded Microsoft’s AI Red Team, asked the chief technology officer of the UK government’s AI Security Institute where she oversees safety evaluations for the latest-generation or “frontier” AI models, Jade Leung to respond.
Leung, who previously led the governance team at OpenAI, said that while “building fast” remains essential, so too does “building competently,” because safety, security and opportunity remain inextricably intertwined.
Unless AI models have a proven safety and security track record that’s based on an empirically sound foundation, they’re going to face adoption challenges, both by enterprises as well as governments who need to beware national security concerns – covering such domains as chemical, biological, cybersecurity and human influence – she said.
“Clearly, capabilities are moving much faster than safety and security. I think there’s a sense from individuals in the field that we’re barely keeping up,” although doing so is mandatory for finding the right kinds of mitigations, Leung said.
As in many other fields, AI measurement is growing increasingly political. Even so, “when it comes to particularly severe national security risks, my hope is that there’s a kind of gravity to that,” Leung said of the need to build “international consensus” on the need for careful and constant evaluation.
Challenges abound when trying to keep tabs on frontier models’ behavior. “When you start to pre-train a model, you really don’t know what it’s going to be like on the end,” said panelist John “Four” Flynn, vice president of security and privacy at Alphabet’s Google DeepMind research laboratory. Also, “your synthetic test environment doesn’t always replicate what you see in the real world.”
Many AI development teams track performance benchmarks and leaderboards – for example, to record a model’s resistance to prompt injection attacks – throughout the development process. As more agentic systems are designed to make decisions and autonomously execute tasks, he also foresees “a whole slew of privacy issues that will come to the fore” and need to be carefully tracked and managed.
Frontier models increasingly sport “emergent” or “divergent” behaviors for which researchers need to be well-prepared, the AI Security Institute’s Leung said. This includes sandbagging, which refers to some AI models downplaying their capabilities in an evaluation or test environment – versus a real-world deployment – in ways that are difficult to detect. The increased use of AI agent scaffolds, allowing them to pursue more complex tasks or for eliminating common errors or unwanted behavior, also complicates efforts to understand how the models could be misused.
Another challenge is the systems in which AI models are deployed, potentially including networks of agents, must also be assessed, said Daniel Rohrer, vice president for software product security, architecture and research at Nvidia.
On the security front, a model may offer thousands of capabilities, of which an organization may only need to use one, or a handful and thus want to restrict the model accordingly. “That ability to exert control as complexity rises is going to be really important,” Rohrer said.
RSAC Conference panelists said trust in models remains key to their success. Flynn said fostering that sense of trust in how Google’s Gemini family of AI tools gets built remains a major goal for the project team, especially as enterprises try to figure out how much trust they want to place in any given model.
“There’s a lot of work we still have to do to really show our work there,” he said.
The need to prove a model can be trusted is also “going to be doubly true in an agentic world,” he said, given the increased independence granted to AI-driven tools to enable them to make autonomous decisions. “They have increasing access to your enterprise data, they have the ability to make pull calls” from databases, email and other data stores and ‘that level of trust is going to require and imply a trust in the underlying vendor that’s supplying the models that you’re building on.'”
Seeking Better AI Hygiene
Numerous big-picture security questions continue to concern researchers, such as the ability of governments to insert undetectable backdoors into LLMs that could be used “to completely control the input/output behavior of the system,” said a professor of computer science at the Massachusetts Institute of Technology Vinod Vaikuntanathan.
“This is theoretically possible,” he said, while participating in the conference’s annual Cryptographers Panel on April 29. “I very much think this is practically possible as well.”
“It’s going to be a very, very attractive target,” said fellow panelist and cryptographer Adi Shamir, who’s the “S” in the RSA cryptosystem. “Governments like the idea of putting their own backdoors into systems.” Such AI backdoors could be used to sabotage facial recognition systems, to trick the system into assigning someone’s identity to another, or to keep them anonymous – or for any other “government goals,” he said.
The inscrutability of how LLMs function also means that malicious software generation capabilities could easily be hidden inside them, and used to secret backdoors in developers’ applications. “The whole transition from manmade software into AI-based software is extremely dangerous,” Shamir said.
MIT’s Vaikuntanathan said researchers are exploring ways of mitigating the effect of any backdoors that have been inserted, without having to detect them first. One strategy repeatedly mooted at RSAC Conference was designing AI tools to keep tabs on other AI tools, to ensure they don’t misbehave.
From a safety standpoint, Vaikuntanathan said the desired outcome from such oversight tools is akin to regularly washing hands. “You don’t know if your hands have germs or not, it’s undetectable, but you wash your hands anyway, and if your hands have germs, they get clean and if your hands are clean to begin with, they’re still clean.”
Researchers emphasized that the collective goal isn’t handwringing but rather to find fresh ways to ensure AI tools remain safe, reliable and secure. “We think the attack surface is growing fast, and we have to spend a lot more effort trying to understand it,” Vaikuntanathan said.